CONFIGURABLE TRANSFORMER FOUNDATIONS
Native Transformer architectures and versioned experimental configurations.
GAVRIEL.TECH // SYSTEM STATUS
Preparing the interface and loading the next system state.
// PLEASE STAND BYExperimental MicroModel Architecture
MACHINE INTELLIGENCE / TRANSFORMER ARCHITECTURE / CONTINUAL LEARNING
An experimental architecture and development laboratory for persistent, modular, agent-oriented MicroModels.
EMMA explores how independently owned MicroModels can learn from verified experience, retain useful capabilities, and cooperate through separately versioned components. The first prototype now learns during operation in separately owned parameters, acquires a new capability through verified capability transfer, and combines memory with learned estimates, each measured on sealed data.
EMMA LABS is the platform and research environment. EMMA Native Foundation 001 is a model lineage developed within it.
Screenshots of the operational EMMA interface. Select a screenshot to enlarge it.
EMMA investigates how small MicroModels can accumulate useful capabilities while preserving previously learned behavior.
The project brings together Transformer Foundation development, component-scoped training, AdaptiveWeight Units, Context Drones, Global Context, persistent Memory, and independent Decision and reasoning MicroModels.
EMMA LABS supplies the infrastructure to construct these systems, inspect their behavior, and evaluate changes before activation. Current results cover one task family with executable ground truth: inspecting small neural-network training runs and predicting their outcomes. General continual learning and transfer to broader engineering work remain research goals.
Convert verified experience into persistent, independently learned MicroModel capabilities. Preserve acquired knowledge and behavior across sessions. Coordinate Context Drones, Memory, AdaptiveWeight Units, and Decision and reasoning MicroModels. Enforce regression controls to protect validated capabilities during ongoing adaptation.
The first prototype is an operating system of composable MicroModels. Each capability is tested against a gate that is locked before results are known, on sealed data scored once. A candidate that misses its gate is recorded as failed, even when it holds the best measured score.
A 3,374-parameter composition predicts training-run failure at 85.5% on 800 sealed runs; a flat neural control scores 86.4%, so no accuracy advantage is claimed. A frozen member is reused unchanged in a second composition.
JOURNAL79.4% versus 72.1% frozen on 800 sealed runs. Older answers bit-identical. A unit trained on shuffled outcomes was not promoted.
JOURNAL35.7% to 81.5% from 400 shown examples. Source Model answers verified before use; all 38 wrong answers refused. One binary task; the person was simulated.
JOURNAL83.7% with self-selected uncertain cases versus 75.2% with the same number chosen at random, on 600 sealed runs.
JOURNALFive rounds of feedback raised sealed accuracy from 71.7% to 79.0%. All 20 incorrect corrections were refused by verification.
JOURNALLearned estimate 77.6%; 83.4% and 87.7% with three and five remembered runs. Exact recall 100 of 100 without execution.
JOURNAL91.5% of texts with every field correct on the sealed set, and 83.0% on a later reserved set. Unreliable readings are refused.
JOURNAL97.6% on 800 sealed runs after 120 of 200 training steps. The measured upper bound at that point is 99.2%.
JOURNAL88.2% on a sealed theme never trained, against 43.0% for a single-head reference; wrong operation 5.2%. All nine gates passed. A later version (V78.7) failed and left the reserved questions unopened.
JOURNAL83.1% against 79.2% frozen on 6,000 sealed runs, +3.9 points against a 3-point gate. Deficit regimes +6.3 and +7.4; no regime more than 0.4 points lower. Units are applied only where they proved better.
JOURNAL93.4% on a fresh sealed theme with no exact request answered more loosely, against gates of 80% and at most 3% (V85.10). The learned part alone scores 84.3%. In the operating path, 60 of 60 exact requests were right and no unmatched request received a value (V92.1).
JOURNAL88.9% of questions right on six sealed technical dossiers of about 51,000 tokens, against 38.9% for the best baseline (V116). In the demonstration, 36 of 36 long-document questions right with cited evidence (V118.3).
JOURNAL78.2% to 82.9% on 3,000 sealed configurations, 2.1 points above an online-learning control, with no forgetting of earlier regimes and no training run.
JOURNALFrom a mixed stream with no needs supplied, the system found two needs, met each by reuse, and gained 2.8 and 2.7 points on fresh sealed sets with everything outside unchanged (V100.3, V100.4).
JOURNALNo wrong commit on 109 sealed calculation questions; 42 of 42 multi-step questions answered, and 19 of 32 held-out question kinds, with the rest withheld (V119, V122).
JOURNAL87.5% to 89.1% on 1,371 configurations never executed; the paired test gave p = 0.061 against a locked 0.05 gate, so no gain is claimed (V124.1).
JOURNALThe reader’s encoder loads through the block store by byte range, checked tensor by tensor, from a bounded cache; outputs are bit-identical to a whole-file load and a damaged cache entry is fetched again. Every answer lists each executed component with its size.
JOURNALA composition used as one member of another reached 84.0% on 1,000 sealed runs with three trained values, against 78.0% and 80.0% for its members and 82.6% for boosted trees.
JOURNALThe top proposed change fixed 74.3% of 400 failing runs when executed, against 28.5% for a random candidate. Nothing is committed until execution shows progress.
JOURNAL0 of 12 planted attacks learned or remembered, every exact answer right, one unit promoted from 2,440 self-verified outcomes, peak memory 13.2 GB on one desktop computer. Scripted visitors (V98.1).
JOURNALAll figures come from one task family and are documented with their controls and limits in the linked journals. Experiments ran on a single workstation with a 4 GB graphics processor: general reading ability comes from pretrained weights, frozen or fine-tuned in the laboratory, and learned units of a few hundred parameters train on the central processor. Status as of October 28, 2026.
EMMA LABS provides the environment for constructing, training, inspecting, and evaluating MicroModels and their components.
Native Transformer architectures and versioned experimental configurations.
Targetable attention, FFN, and transformer-block components for scoped adaptation and inspection.
Declared training scopes for AdaptiveWeight Units, Decision MicroModels, and other candidate components before activation.
Controlled gates for acceptance, rejection, and restoration of a verified prior version. Rejected research candidates remain separate from active execution.
Versioned artifacts, base-version identities, integrity checks, and traceable MicroModel development.
Independent Context sources, a separate task workspace G, and persistent Memory with temporal history and corrections.
Source Model integrations, verified demonstrations, recorded task outcomes, and bounded ToolDecision workflows.
Model, component, training, and resource observability.
Browser-based tools for inspecting MicroModels, running experiments, and stepping through bounded workflows and the integrated agent baseline.
Native Transformer architectures and versioned experimental configurations.
Targetable attention, FFN, and transformer-block components for scoped adaptation and inspection.
Browser-based tools for inspecting MicroModels, running experiments, and stepping through bounded workflows and the integrated agent baseline.
Declared training scopes for AdaptiveWeight Units, Decision MicroModels, and other candidate components before activation.
Controlled gates for acceptance, rejection, and restoration of a verified prior version. Rejected research candidates remain separate from active execution.
Versioned artifacts, base-version identities, integrity checks, and traceable MicroModel development.
Independent Context sources, a separate task workspace G, and persistent Memory with temporal history and corrections.
Source Model integrations, verified demonstrations, recorded task outcomes, and bounded ToolDecision workflows.
Model, component, training, and resource observability.
These systems make development observable and reversible, from an individual component update to a complete experimental MicroModel configuration.
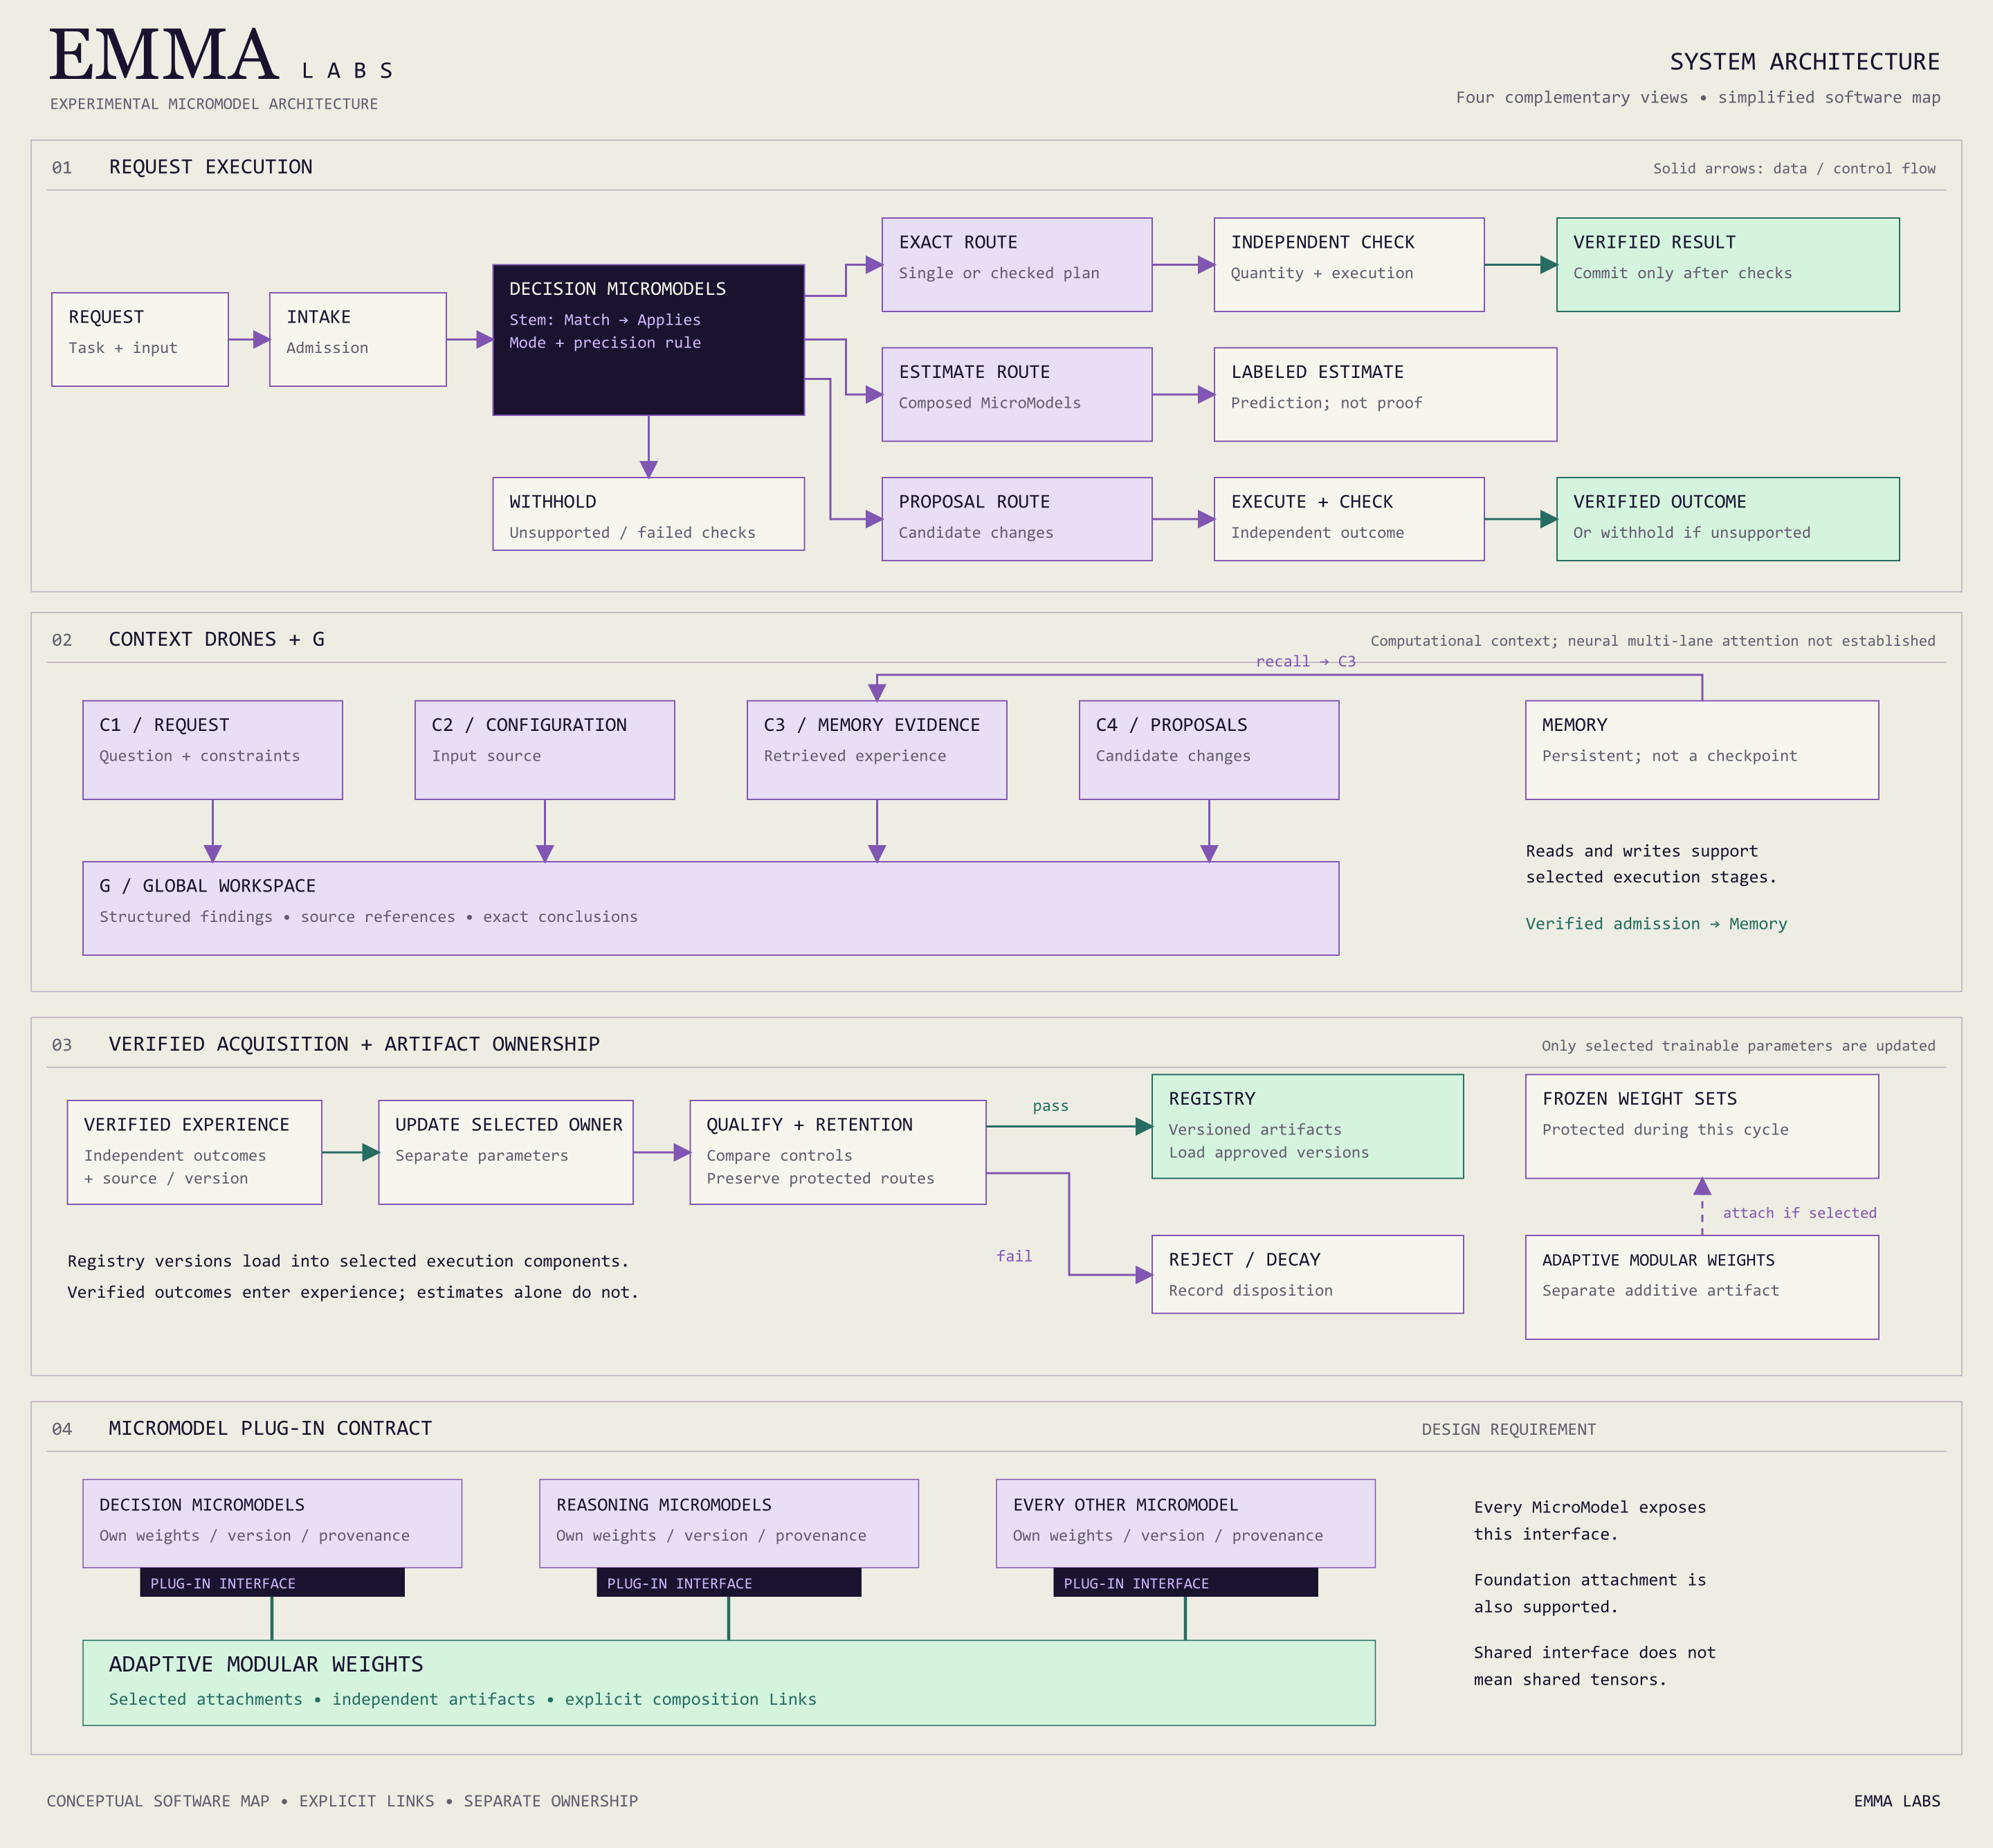
EMMA separates generative intelligence, Context, Memory, bounded decisions, and training into systems with explicit responsibilities.
C1 · C2 · C3 · C4
Independent information sourcesObjective · Constraints · Plan · State
Separate active-task workspaceVerified events · Corrections · Recall
Explicit promotion of relevant facts into GAddressable attention / FFN / blocks
Evidence · Tools · Context · Multi-step reasoning
Independent parameters and lifecyclesOutputs · Tool actions · Provenance
Model and resource telemetryCheckpoint · Restore · Revalidate
Rollback to a verified prior version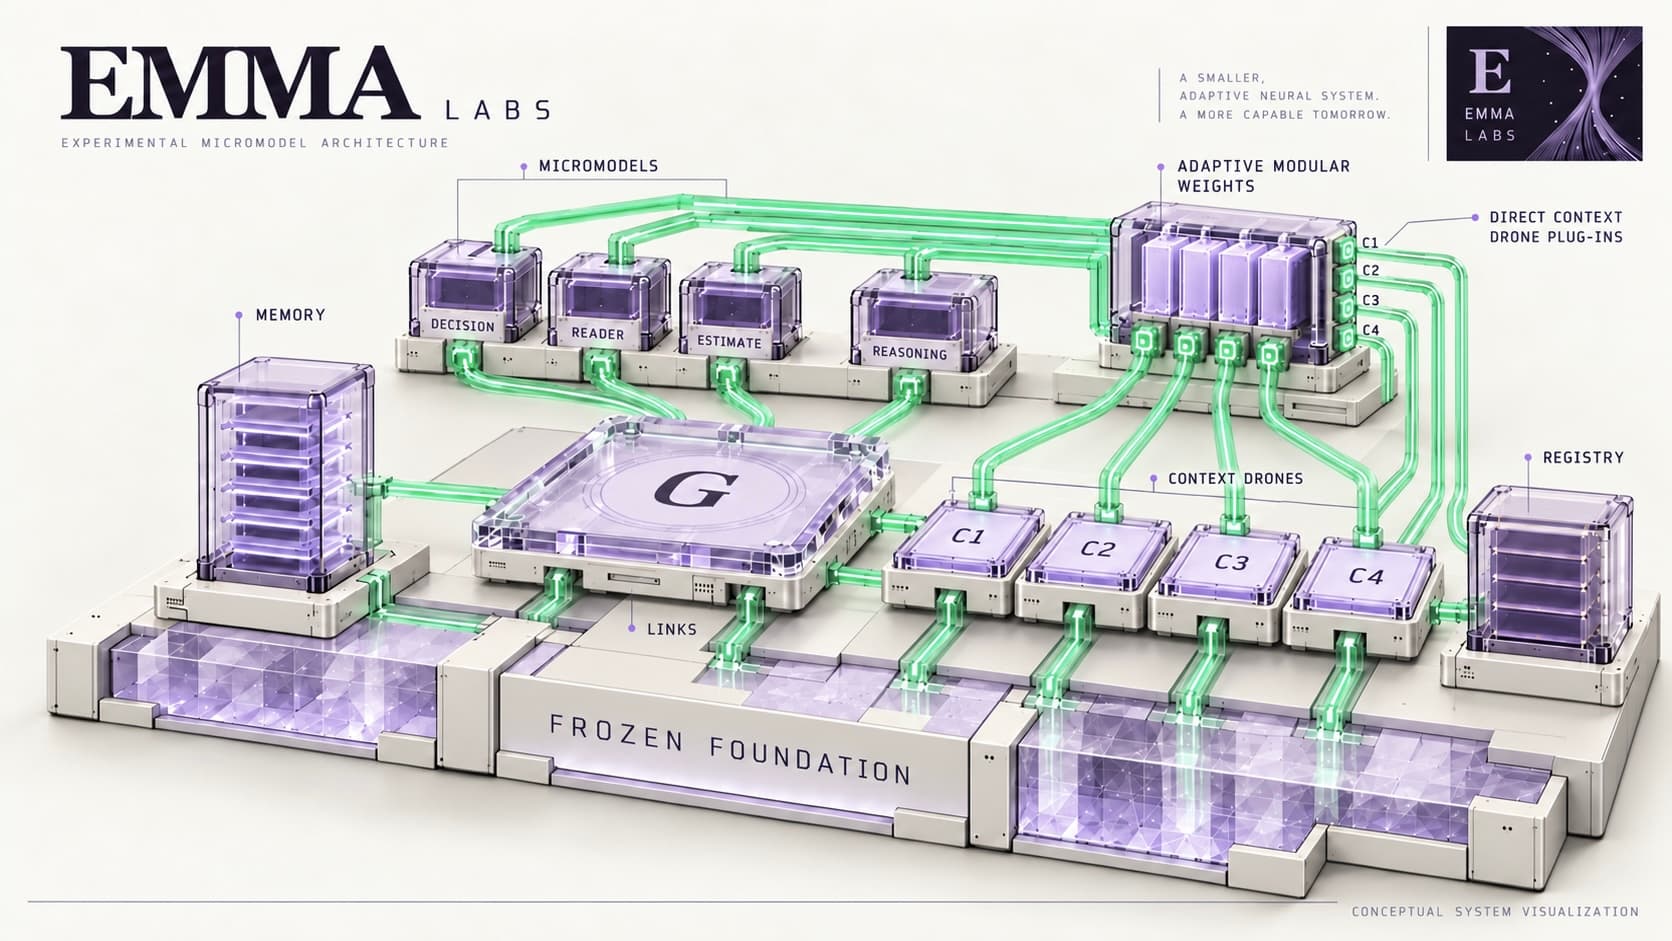
The underlying generative MicroModel, with addressable attention, FFN, and transformer-block components. EMMA Native Foundation 001 provides the native eight-block baseline. Qualified checkpoints remain immutable controls, with development continuing through separate versions.
Separately trainable weight components attached to declared Transformer Foundation targets. Their learned changes remain separate from stable Foundation weights. AdaptiveWeightModule provides an addressable artifact boundary for one adaptive component or a declared composition; each requires its own validation.
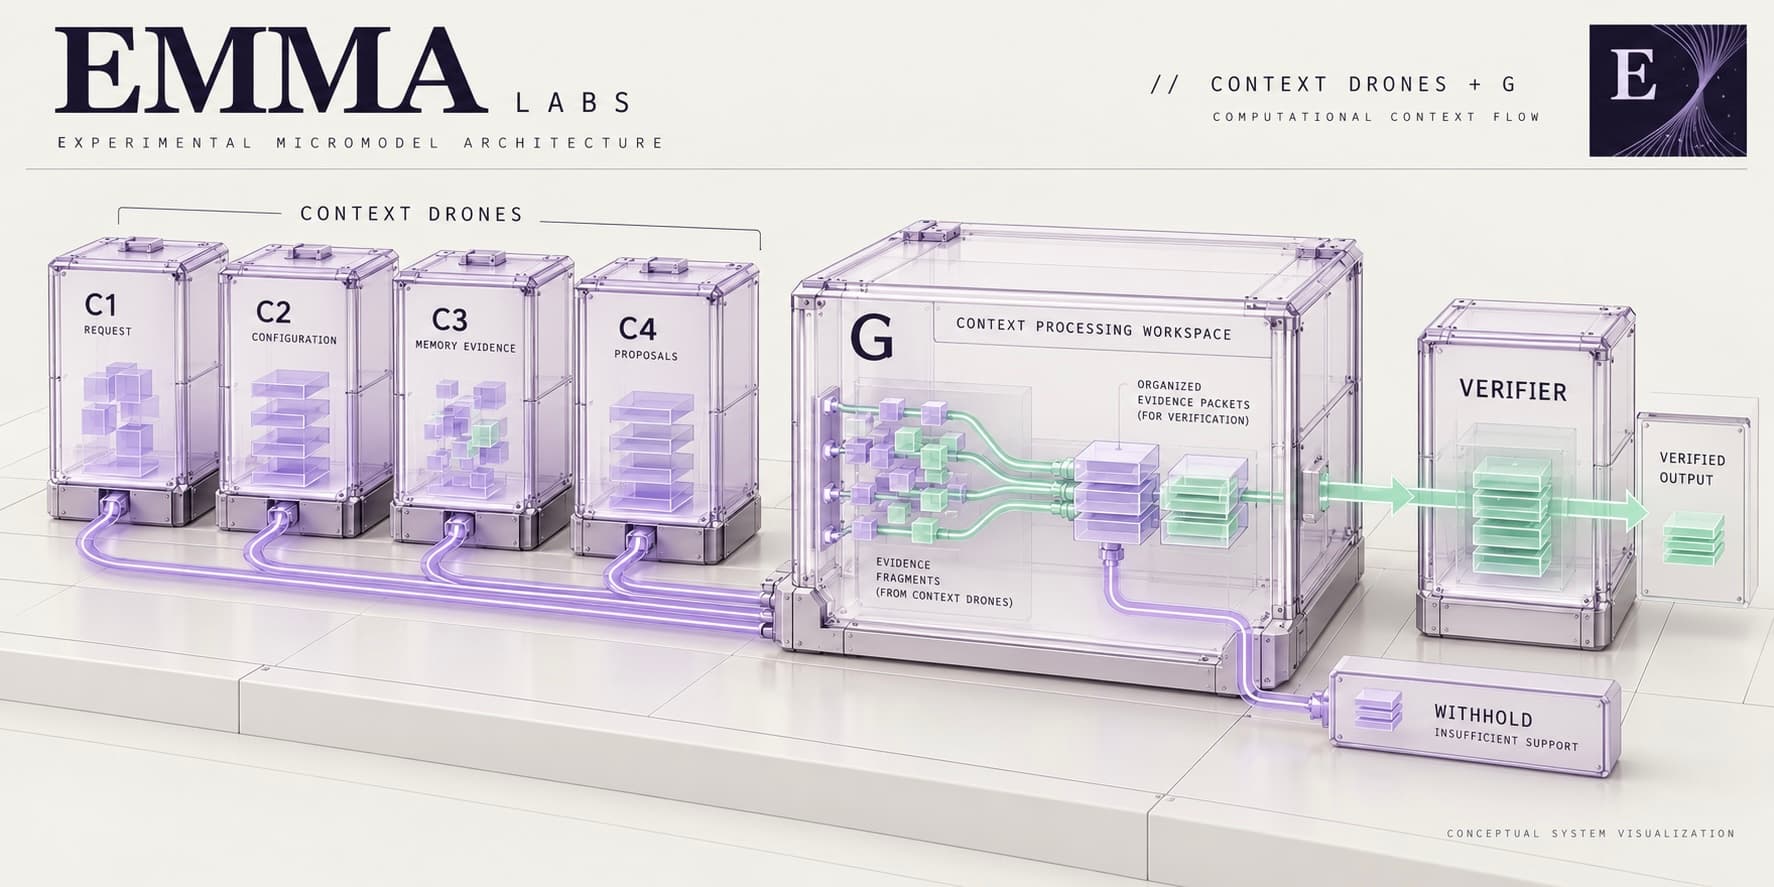
Independently maintained information views with their own identity, focus, source version, provenance, and cached state. A Context Drone holds information; the reader or MicroModel operating on it performs computation.
A separate workspace for the active task’s objective, constraints, plan, and important cross-Drone information. It remains distinct from individual Context Drones and long-term Memory.
Retained experience and verified observations, including temporal history, corrections, provenance, and retrieval. Relevant facts can be explicitly promoted into G while historical observations remain separately preserved.
Independently trained models for bounded choices, with separate parameters, objectives, metrics, artifacts, and lifecycles. Examples include ContextSourceDecision, EvidenceResolutionDecision, and ToolDecision. Reasoning MicroModels plan multi-step calculations as checkable steps; an answer is committed only when every step and the plan’s coverage of the question are verified, and anything that cannot be confirmed is withheld.
A controlled candidate lifecycle that evaluates scoped changes before promotion and preserves a path back to a verified prior version.
The forward architecture of cooperating MicroModels, learned Link Modules, and versioned Module Sets is shown separately in 08 / DIRECTION.
A compact native transformer trained from initialization as a controlled baseline for architecture and adaptation experiments.
The original qualification recorded 155 exact responses across 160 retention and hidden examples.
The qualified checkpoint remains an immutable control. Development continues through separately versioned derivatives and additional components.
These measurements describe the original bounded qualification. They do not represent general language or autonomous-agent performance, or the combined resource use of later modules.
Preserve experiment evidence
Checkpoint → Restore / Restart → Revalidate
REGRESSION → ROLLBACK TO VERIFIED PRIOR VERSION
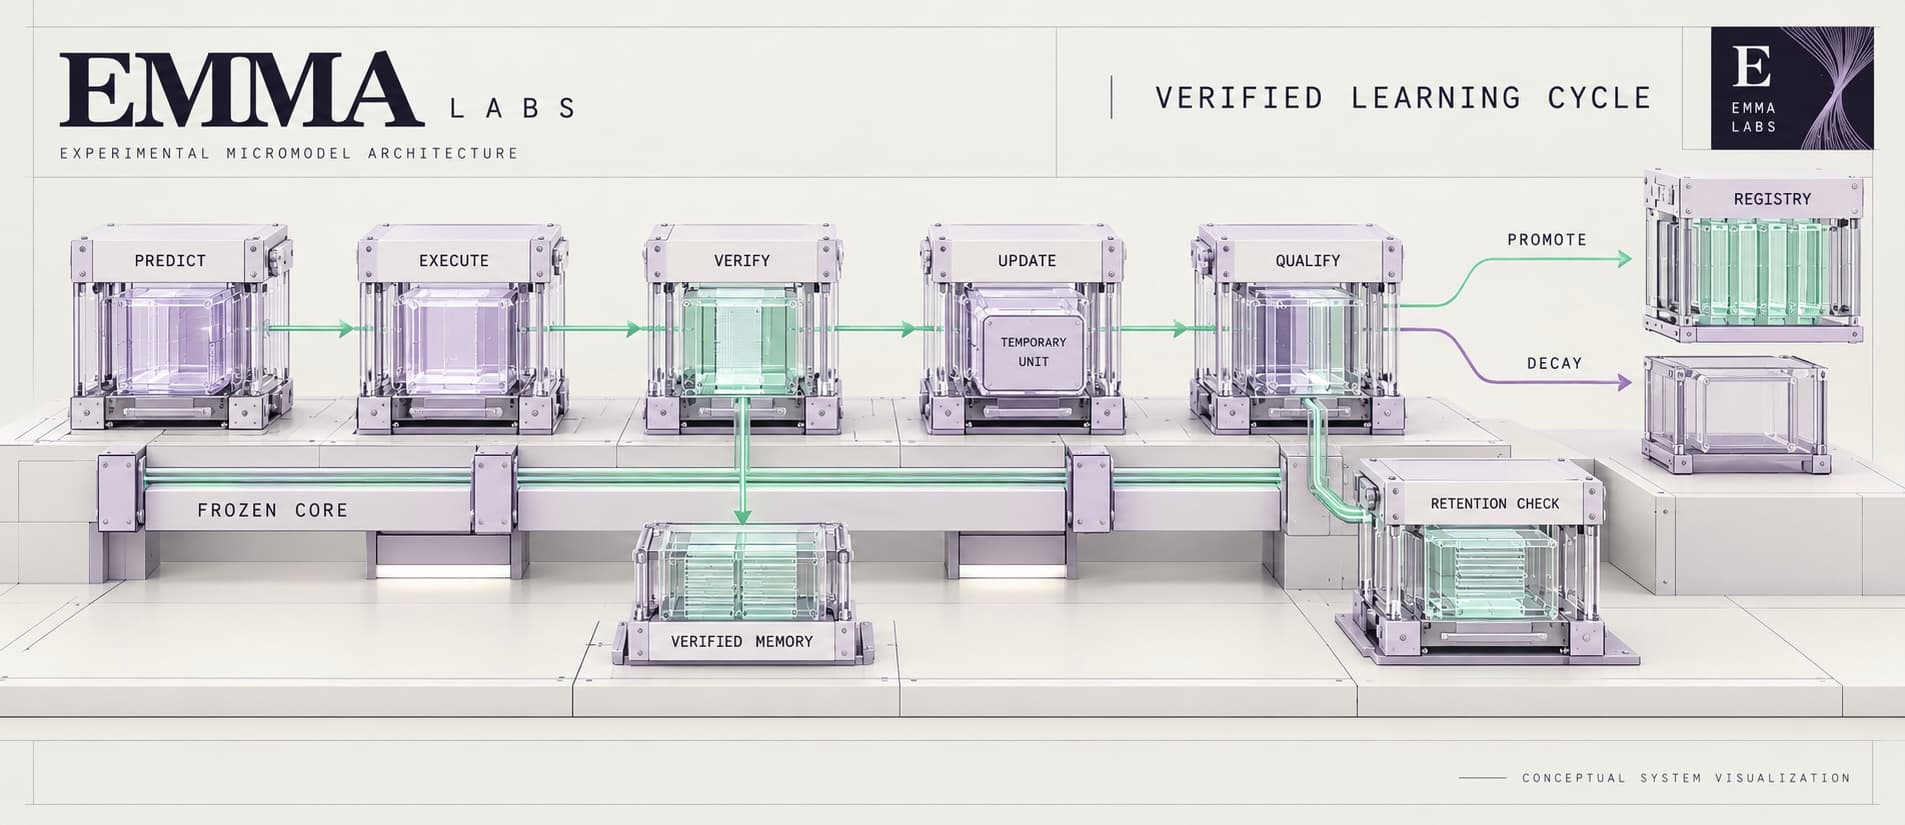
EMMA treats learning as a controlled engineering process. Verified demonstrations and task outcomes can become training material for the responsible MicroModel or component. The candidate’s optimizer scope determines exactly which parameters may change.
Training occurs on an isolated candidate, which must pass the relevant checks before replacing an active version. Qualified source artifacts remain preserved, and rollback remains available when an update causes regression.
The platform has demonstrated bounded persistent learning in Decision MicroModels, including EvidenceResolutionDecision and a constrained multi-step ToolDecision workflow.
V69.1 adds a separately owned temporary unit that learns from verified outcomes while preserving a frozen composition. V79.2 moves that learning into the running prototype: a 305-parameter unit trained during operation, was validated on outcomes held out of its training, and was promoted by the prototype's own rule. A unit must beat the frozen estimate, a base-rate correction, and the majority outcome before promotion.
V83 starts a zero-initialized MicroModel and trains it from shown examples, a stated rule, a Source Model, and user feedback. Independent execution checks what it is given, so a wrong Source Model answer or a wrong correction is refused instead of learned. Each qualification belongs to the tested regime and task.
V78.6 qualifies two linked Decisions with separately owned, replaceable weights: one proposes the operation a request asks for, the other checks that it applies. On a sealed theme that no weight set was trained on, the pair answers 88.2% of questions correctly. V85 measures where a learned output-mode Decision adds to a rule: when a request matches no registered operation, the rule cannot answer and the learned Decision can.
V82.5 qualifies learning the prototype directs itself: it finds where its own estimates fall short, trains a unit for that region, and applies the unit only where held-out outcomes show it is better. In the live demonstration the same mechanism learns between visitor turns from outcomes the system executes and checks itself, so nothing a visitor says is learned directly (V90, V98.1).
V119 to V122 add checked multi-step reasoning. EMMA’s own reasoning MicroModel plans a calculation as steps, and an answer is committed only when every step and the plan’s coverage of the question are verified. On 109 sealed questions no wrong answer was committed: all 42 multi-step questions were answered, and with a second stage consulted only where the first withholds, 19 of 32 question kinds never trained on were answered and the rest withheld. Checked reasoning has run in the live demonstration by default since October 27.
From V99 to V108.1 the system finds its own needs in a stream of verified outcomes, meets them by reusing or linking what it already has, and attaches nothing without a recorded decision, while a separate component learns from every verified outcome without forgetting earlier regimes. A learner added in V123 raised accuracy on configurations the system had never executed, but the gain did not clear its locked significance test (V124.1), so no such gain is claimed.
Inspect components. Declare update scope. Preserve version lineage.
Native Transformer Foundations, component-scoped training, AdaptiveWeight Units, and independent Decision and reasoning MicroModels.
Candidate isolation, validation gates, checkpoints, artifact integrity, versioned runtime selection, promotion, and rollback.
Context Drones, Global Context G, persistent Memory, temporal corrections, and source provenance.
Source Model connections, verified task outcomes, bounded ToolDecision workflows, and explicit component selection.
A browser interface for inspecting MicroModels, running experiments, and observing training and resource telemetry.
Compact MicroModels, scoped updates, and measured compute and memory costs.
The next architectural direction extends EMMA beyond adaptations attached to one Transformer Foundation. Independently owned MicroModels are intended to retain their own weights and runtime state, process assigned Context Drones, and communicate through separately versioned Link Modules.
The Foundation is intended to participate as a model node alongside other MicroModels. Learned peer communication and broad Module Set qualification remain research goals.
EMMA agents, called Neuromorphs, are compositions of MicroModels and nodes. Neuromorphs link to other Neuromorphs, and a constellation of linked Neuromorphs forms an EMMA HiveMind.
Separately trained connections that route, gate, project, or transform information between model nodes while preserving qualified endpoint weights.
Versioned compositions that pin model nodes, Link Modules, Context Drone bindings, synchronization points, and resource policies for an operation.
ModuleActivationDecision selects and activates the required modules and links using task, Context Drone, capability, dependency, and resource metadata. The intended runtime loads or dispatches the validated selected set while leaving unselected candidate weights unloaded.
CompositionDecision controls communication topology, synchronization, and execution rounds among active modules. ModuleContributionDecision assigns an independent contribution weight to each active module’s result, allowing several modules to contribute during the same operation.
These describe the forward architecture. Supporting interfaces and bounded composition experiments exist. Reliable AdaptiveWeight composition, learned whole-model cooperation, and the complete decision-controlled modular fabric remain under investigation.
EMMA is designed for work where an incorrect value costs more than a missing one. Every value the system commits is computed and independently checked, and anything it cannot confirm is withheld or returned as a clearly labelled estimate. Because MicroModels are small and run on modest hardware, EMMA can operate offline inside products and facilities, and it keeps learning after deployment from verified input without losing what it could already do. It is built to work alongside large general-purpose models, contributing precise, verified values, durable memory and local operation.
MicroModels inhabit in-game non-player characters in AAA titles. Each character carries its own persistent weights, Memory, and Decision MicroModels, so it can learn from play and keep what it learned between sessions, while staying small enough to run alongside a game engine.
EMMA models drive the behavior of rendered 3D characters, such as the EMMA character model, connecting a visual body to persistent memory and learned decisions.
VIEW THE EMMA 3D CHARACTER MODEL →Planned. Companions and characters that retain what happened with each player across sessions, updating only from events the game itself confirms, sized to share a consumer GPU with the renderer.
Populations of independently owned MicroModels acting as agents in simulations, training environments, and virtual worlds, each with its own state and learned behavior.
Planned. Opponents that adjust to how a player fights while keeping approved tuning, and test agents that play builds and report failures a QA team can reproduce.
Characters and hosts in interactive film, virtual production, and live events that respond to their audience and remember returning participants.
A persistent personal agent that learns and grows with its user. Interactions, corrections, and preferences become part of its own MicroModels and Memory, so its capabilities accumulate over months and years instead of resetting with each session. Every learned change is versioned and reversible, keeping the user in control of what it retains.
Durable personal memory of past conversations, projects, and decisions, with the relevant context brought forward when it is needed.
An agent that learns its user's tools, workflows, and routines, and takes on recurring multi-step tasks once each step has been verified.
In development. Agents that accumulate verified knowledge over months of use and coordinate through shared, validated interfaces. Clients can direct an agent toward their own domain while it is in service.
A creative partner that learns an individual style across writing, music, design, and code, and refines its contributions through feedback.
Planned. Learning tools and support systems whose answers are checked against verified sources before they are shown.
Compact MicroModels that run on the user's own hardware, keeping personal data, memory, and learned behavior under the user's control without a data-center connection.
In development. Parameter recommendations for manufacturing and process equipment that run on site and offline. Each committed setpoint is checked, and every change is versioned so it can be inspected or rolled back.
Separately owned perception, decision, and control MicroModels that coordinate within a machine or fleet, with each component versioned and independently qualified.
Decision MicroModels that select and sequence tools in multi-step business workflows, learning from verified task outcomes.
Bounded decision models for manufacturing automation, security and access control, datacenters, and robotic warehouse systems, where each update is validated before activation and can be rolled back.
MicroModels that learn to detect defects, faults, and anomalies in production lines and infrastructure, each qualified against held-out cases before deployment.
Domains that need a traceable record of how a model changed, served by versioned components, locked qualification gates, and preserved source artifacts.
Planned. Calculations and drafting support in which every figure is verified, projections are labelled as estimates, and a record shows what was checked.
Planned. Deployments in air-gapped or bandwidth-limited settings where cloud services are unavailable and outputs must be traceable.
Planned. Embedded, offline operation with safety-oriented checks.
Planned. Workstations, robots, aerial drones and hardware components that run an AI-first operating system, with EMMA as the precision layer and verified updates delivered from a central system.
Prototype results. EMMA predicts how small neural-network training runs will turn out before they finish, so compute is spent on configurations worth running. This is the task family the first prototype is qualified on today.
Planned. Circuit and system design where component values, tolerances and power budgets must be precise. Calculations that cannot be confirmed are flagged for an engineer before they reach a schematic.
Planned. Every value computed twice, independently.
MicroModels that accumulate verified engineering knowledge and transfer it to broader development work, a stated research goal.
EMMA LABS as an environment for building, training, inspecting, and evaluating modular models with controlled, reversible change.
Planned. A platform that finds the combination of MicroModels best suited to a stated objective and hardware budget, delivered as an embedded system, a cloud service or a licensed deployment.
Locked qualification gates, sealed evaluation data, and regression checks applied to any model before it replaces an active version.
Compact, separately versioned MicroModels packaged for embedded devices and edge hardware with tight memory and compute budgets.
These applications are planned or in development and not yet released as products. Current qualified results cover one task family, inspecting small neural-network training runs and predicting their outcomes. Each application depends on research goals listed in 08 / DIRECTION and 10 / STATUS.
With every component that passed its own gates switched on together, the live demonstration learned nothing from 12 planted attacks, leaked no name, committed no wrong exact value and stayed within 13.3 GB on one desktop computer. A new learner raised accuracy on 1,371 configurations it had never executed from 87.5% to 89.1%, but the paired significance test gave p = 0.061 against a locked 0.05 gate, so no gain on unseen configurations is claimed. A larger test is planned. This configuration is the current freeze candidate.
On 360 sealed questions over 60 fresh documents, the material passed on per question fell from 32.8 items to 2.2 with recall of the needed evidence held at 100%; precision rose from 21.9% to 93.1%, and 359 exact answers were given with none wrong. On two sealed sets of 120 paraphrases written independently of the laboratory’s generator, 110 and 115 questions were answered right with no wrong answer; every miss was withheld.
EMMA’s own small planner answered 42 of 42 multi-step and 10 of 10 direct calculation questions in unseen wording, declined all 15 it should, and committed no wrong answer. Released reference language models used alone committed 6 to 10 wrong answers each; used only where EMMA’s planner withholds and held to the same checks, the selected one answered 19 of 32 held-out question kinds with no wrong commit across 109 sealed questions and no training.
Python / PyTorch / CUDA / custom transformers / AdamW / distillation / LoRA / experience replay
FastAPI / WebSockets / SQLite / versioned artifacts / checkpoint management
Next.js / React / TypeScript / model graphs / telemetry / pytest / Playwright
EMMA’s research records document the experiments behind the platform: what worked, what failed, how results were measured, and which questions remain open.
Every entry in the prototype status above links to its journal. Explore Transformer Foundation qualification, AdaptiveWeight Unit experiments, Context Drone integration, Global Context, persistent Memory, Decision MicroModel learning, and modular cooperation. Detailed results, controls, qualification limits, and experimental lineage belong in the research records.